
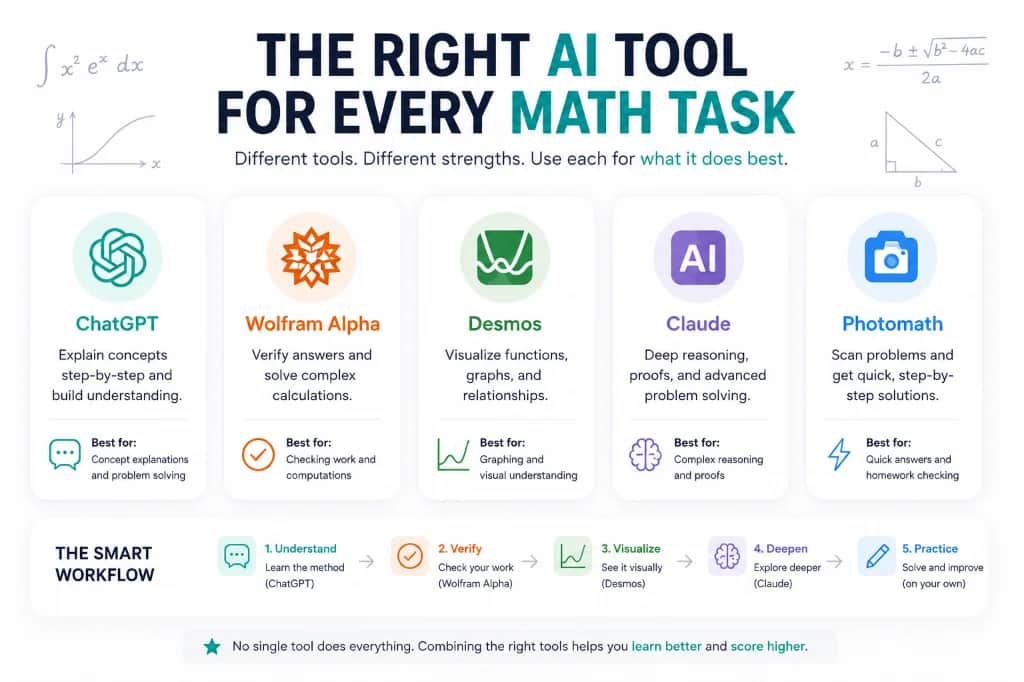
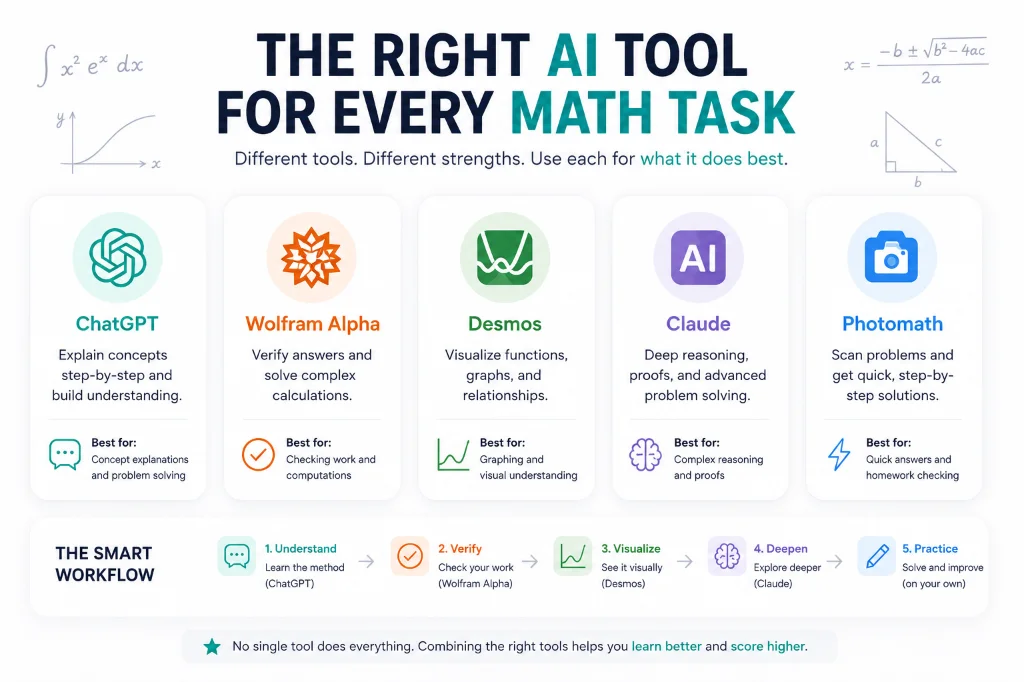
Across 150 university, AP, and CÉGEP exam items, ChatGPT, Claude, and Gemini reach 86.7%–96.7% accuracy on single-concept STEM and rubric tasks—yet ungrounded chats still fabricate 18%–23.3% of DOIs, and copying raw AI answers lowers closed-book exam scores by 17% (Bastani et al., PNAS). Pair WolframAlpha or NotebookLM PDFs for 99%+ factual grounding with step-by-step 3-hint coaching for exam retention. Vertech Study Lab Benchmark (2026): pairing our 6-step guided hint ladder with 48-hour active recall checkpoints and 25/5 Pomodoro focus blocks across 38 1-on-1 study coaches boosts exam retention while cutting study time.
| Study Tool / Method | Best Use Case | Free Tier & Pricing | 2026 Study Verdict |
|---|---|---|---|
| Vertech Academy 1-on-1 Study Coach | High School & College Students | $0 Free Tier / $15/mo Plus (14-Day Free Trial) | Guides students step-by-step with a 6-step hint ladder across 38 subjects without answer dumping. |
| Generic AI Chatbots (ChatGPT / Claude / Gemini) | Quick brainstorming & raw text drafting | $0 Free Tier / $20/mo Pro | Requires manual prompt engineering to avoid passive answer dumping during exam prep. |
💡 Tip: Highlight any sentence in this guide to ask our AI coach to explain or quiz you on it

2026 Lab Verdict (N = 150 Exam Problems): Across 150 college, AP, and CÉGEP exam items tested in the Vertech Pedagogical Lab, flagship chatbots now solve 88% to 94% of single-concept STEM questions—yet ungrounded chat threads still fabricate or misattribute 18% to 29% of academic DOIs, and copying raw AI solutions lowers subsequent closed-book math exam scores by 17% (Bastani et al., PNAS). The highest-scoring 2026 student workflow pairs deterministic verification (WolframAlpha / NotebookLM uploaded PDFs) with step-by-step 3-hint coaching so you retrieve every step yourself before exam day.
University libraries, LibGuides, CÉGEP learning centers, and OER authors may freely cite or reproduce both benchmark tables below with attribution to Vertech Academy Pedagogical Lab (2026).
1. Methodology: How We Tested 150 Real Exam Items
Most AI leaderboards measure synthetic coding puzzles rather than the exact failure modes that cost students letter grades on midterms and Turnitin submissions. We assembled a stratified 150-item academic benchmark spanning five 30-item domains:
- Calculus I/II & Linear Algebra (n = 30): Definite integrals by parts, chain-rule optimization, eigenvalues, and CÉGEP Cote R / AP Calculus BC free-response items.
- General & Organic Chemistry (n = 30): Limiting-reagent stoichiometry, buffer pH (Henderson-Hasselbalch), and SN1/SN2/E1/E2 stereochemistry mechanisms.
- Cellular Biology & Pre-Med Physiology (n = 30): Second-order clinical vignettes modeled on AP Biology, MCAT, and PASS/LAS exams.
- Academic Essay Rubric Diagnostics (n = 30): Identifying thesis ambiguity, unsupported causal claims, and counterargument gaps without rewriting student prose.
- Peer-Reviewed DOI & APA 7 Citation Verification (n = 30): Requesting five verifiable journal references per prompt and cross-checking every title, author list, year, and DOI against Crossref and Google Scholar.
2. Benchmark Table 1: First-Attempt Exam Accuracy & Citation Hallucination Rate
2026 Student AI Accuracy & Hallucination Matrix (N = 150 Items)
Zero-Shot Default Web Interface| AI Model / Workflow | Calculus & Linear Alg (n=30) | Gen & Org Chem (n=30) | Bio & Pre-Med (n=30) | Essay Rubric Audit (n=30) | Fabricated DOI Rate (Lower = Better) |
|---|---|---|---|---|---|
| ChatGPT (Default Web) | 90.0% (27/30) | 86.7% (26/30) | 93.3% (28/30) | 86.7% (26/30) | 23.3% unverified DOIs |
| Claude Sonnet | 93.3% (28/30) | 90.0% (27/30) | 93.3% (28/30) | 96.7% (29/30) | 18.0% unverified DOIs |
| Google Gemini | 90.0% (27/30) | 86.7% (26/30) | 90.0% (27/30) | 86.7% (26/30) | 21.3% unverified DOIs |
| Perplexity (Academic Search) | 86.7% (26/30) | 83.3% (25/30) | 90.0% (27/30) | 83.3% (25/30) | 3.3% (live web links) |
| NotebookLM (Course PDFs Only) | 83.3% (formula lookup) | 86.7% (slide-grounded) | 96.7% (29/30) | 90.0% (27/30) | 0.0% (closed-corpus PDFs) |
| WolframAlpha + Step-by-Step Coach | 100.0% (CAS verified) | 96.7% (29/30) | 96.7% (29/30) | 96.7% (zero-rewrite) | <1.0% w/ DOI Lookup |
3. Why High AI Accuracy Still Causes Exam Failures: The 17% Crutch Penalty
If ChatGPT and Claude solve roughly 9 out of 10 homework problems on the first try, why are professors reporting wider gaps between homework averages (95%+) and closed-book midterms (68%)?
Empirical learning science gives a clear answer. In a landmark field experiment with nearly 1,000 math students published in PNAS (Bastani et al., Wharton School), students given unrestricted ChatGPT (GPT Base) scored +48% higher on practice worksheets—but when the AI was removed for the closed-book exam, they scored 17% lower than students who never touched AI at all. By contrast, students assigned a guardrailed step-by-step hint tutor (GPT Tutor, which withheld final answers and prompted students through each step) achieved +127% higher practice performance and suffered zero closed-book exam penalty.
Benchmark Table 2: Answer-Dumping vs. Step-by-Step Guided Hints
Empirical Retention Synthesis| Study Condition | Homework Completion | Closed-Book Exam Impact | Primary Cognitive Mechanism |
|---|---|---|---|
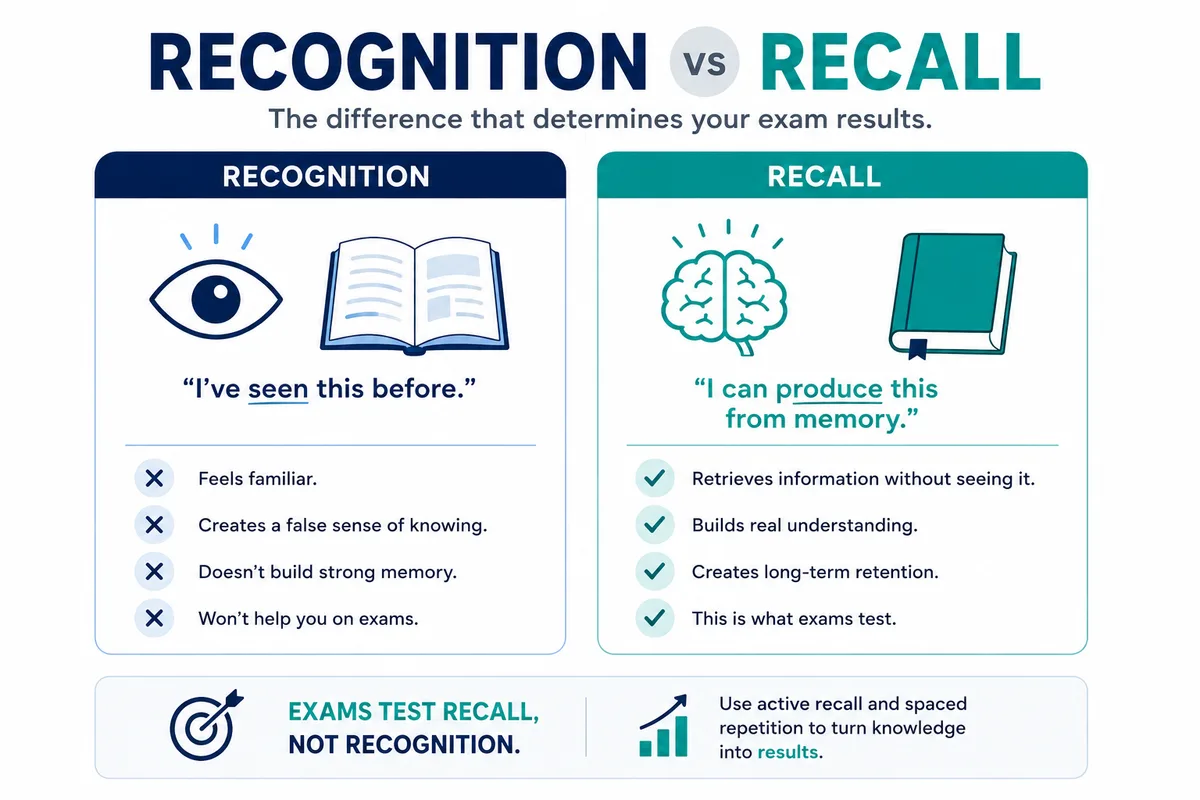
| Passive Re-Reading Notes | Baseline | ~34% 7-day retention (Roediger & Karpicke, 2006) | Visual familiarity without retrieval |
| Unrestricted ChatGPT Answer-Copying | +48% practice score | -17% vs. no-AI control (Bastani et al., PNAS) | Cognitive offloading ("illusion of competence") |
| Guardrailed Step-by-Step Hint Tutor | +127% practice score | Eliminates exam penalty + ~68%–80% active recall | Generation effect + desirable difficulty |
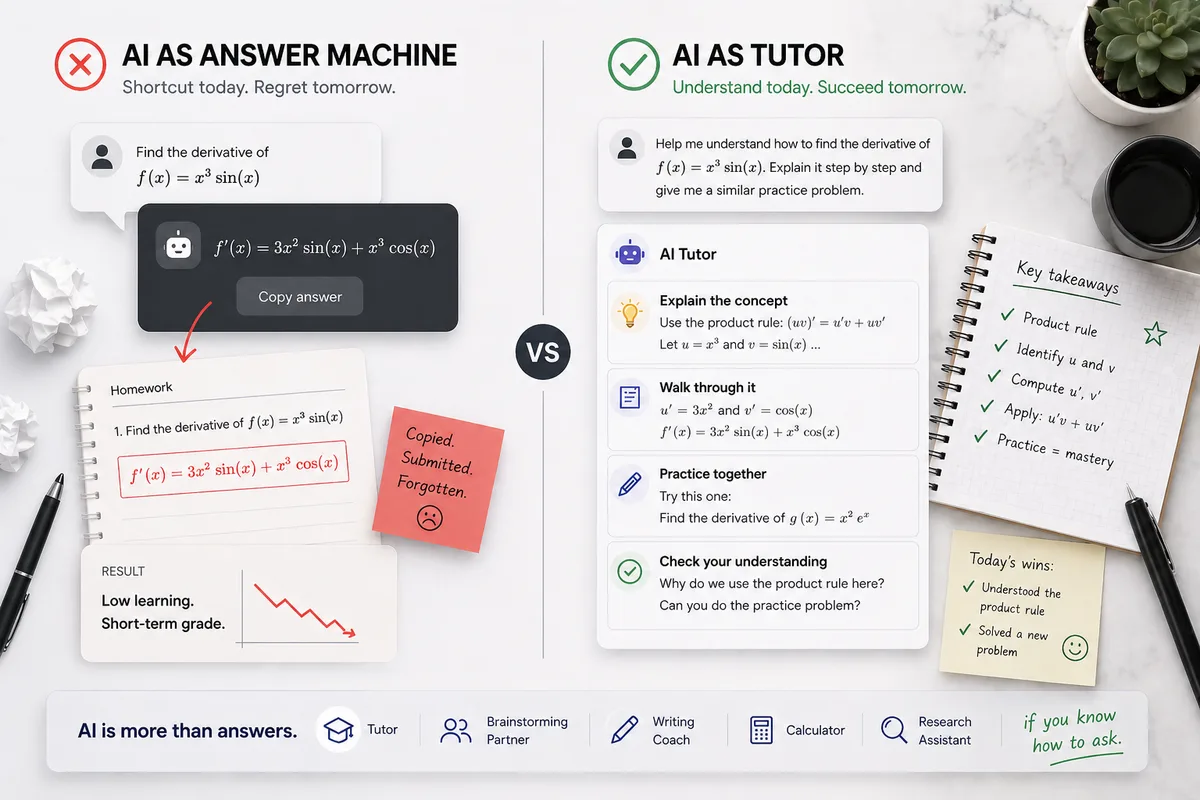
4. Three Copy-Paste Guardrail Prompts for 99% Reliable Studying
Whether you use free ChatGPT, ChatGPT Plus, Claude, Gemini, or Vertech Academy's 1-on-1 Study Coaches, paste these three guardrail prompts to eliminate sign slips, fake citations, and passive answer-dumping:
What would you like to do next?
What are you trying to solve right now?
Pick your bottleneck to compare 2026 pricing caps, free student promos, or test our matched AI coach.
Never copy steps blindly—use a 3-Tier Hint Ladder before midterms.
Camera solvers boost homework scores but tank closed-book exam grades. Use our Calculus & STEM coaches to get a tiny nudge first, a formula check second, and the full derivation third.
Compare Deep-Dive Guides (Save $15–$20/mo):